Why Data Quality Matters More Than Data Volume for LLM Training
16 Sep, 2026
5 Views 0 Like(s)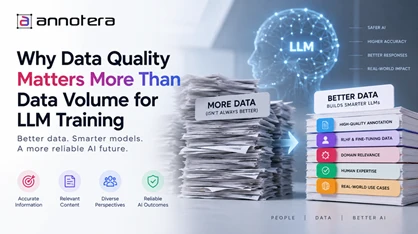
High-quality data helps LLMs learn accurate, relevant, diverse, and reliable patterns. Effective annotation, curation, and validation can improve training efficiency, model performance, and AI outcomes beyond data volume alone.
Large language models (LLMs) are often associated with massive datasets containing billions or even trillions of tokens. While training volume remains important, simply increasing the amount of data does not guarantee better model performance. The quality, relevance, diversity, and accuracy of training data can have an equally significant—and in some cases greater—impact on what an LLM learns.
Recent research has increasingly examined data quality as an explicit factor in language-model scaling. Studies presented at ICLR 2026 found that data-quality interventions such as deduplication and filtering can materially change scaling behavior and compute-efficient training strategies.
For AI companies, this creates an important shift: instead of asking only, “How much data do we have?”, teams must also ask, “How valuable is every training example?”
Data Volume Alone Does Not Guarantee Better LLMs
Data volume refers to the sheer amount of information available for model training—documents, tokens, conversations, prompts, responses, code samples, or other examples. More data can expose a model to additional language patterns and knowledge, but raw volume can also introduce redundancy and noise.
Large web-scale datasets may contain duplicate pages, low-value content, outdated information, irrelevant text, formatting errors, and contradictory statements. Feeding these examples directly into an LLM pipeline can reduce training efficiency and make it harder for the model to learn useful patterns.
Research on data filtering has demonstrated that the value of training examples can change depending on factors such as dataset size, repetition, and available compute. In other words, more data is not automatically more useful data.
What Makes LLM Training Data High Quality?
High-quality training data is not defined by a single metric. It generally combines several characteristics that make examples useful, reliable, and representative.
1. Accuracy and Factual Reliability
Incorrect information can become part of the statistical patterns an LLM learns. Training datasets should therefore be evaluated for factual consistency, especially when they support specialized applications such as finance, healthcare, legal technology, or enterprise knowledge systems.
Human review and automated validation can help identify questionable examples before they enter the training pipeline.
2. Relevance
A dataset should reflect the capabilities and use cases the model is expected to support. An enormous collection of unrelated information may contribute fewer useful learning signals than a smaller dataset closely aligned with the target domain.
For example, an enterprise chatbot may benefit more from accurately annotated customer-support conversations and domain-specific instructions than from large quantities of unrelated web content.
3. Diversity
Quality does not mean making every example look the same. LLM datasets should contain meaningful variation in language, terminology, writing styles, domains, user intents, and difficulty levels.
Diverse data can help models generalize across different contexts instead of becoming overly specialized around repetitive patterns.
4. Uniqueness and Deduplication
Duplicate and near-duplicate examples can inflate token counts without providing equivalent amounts of new information. Large-scale deduplication is therefore an important component of LLM data preparation.
Near-duplicate content can also create risks around memorization and benchmark contamination. Large-scale language-data projects have specifically identified duplication as an important data-quality concern.
Why Annotation Plays a Critical Role
Raw data is rarely ready for every LLM training objective. Annotation adds structure and human-defined signals that allow training datasets to represent specific instructions, intents, preferences, relationships, and response characteristics.
For example, annotators may classify:
-
User intent and task type
-
Question-answer relevance
-
Response helpfulness
-
Factual correctness
-
Toxic or unsafe content
-
Sentiment and emotion
-
Instruction-following quality
-
Preference between competing responses
-
Domain-specific terminology
-
Reasoning or response characteristics
This structured information can make training examples more useful because the dataset is designed around the model's intended behavior rather than simply its size.
Organizations developing specialized AI systems can use LLM & GenAI annotation services to build consistent datasets for instruction tuning, evaluation, preference modeling, and other stages of the model-development lifecycle.
The Role of RLHF & Fine-Tuning Data
Data quality becomes especially important during post-training. Unlike broad pretraining corpora, fine-tuning datasets are often designed around specific behaviors and tasks.
RLHF & fine-tuning data can include demonstrations, ranked responses, preference pairs, corrections, critiques, and task-specific examples. A small inconsistency in these datasets can influence how a model responds to users.
Consider a preference dataset containing two responses to the same prompt. If annotators consistently select the response that is accurate, relevant, concise, and aligned with the desired guidelines, the resulting preference signal becomes more meaningful. If the judgments are inconsistent, the model receives conflicting signals.
This is why annotation guidelines, reviewer training, multiple-reviewer workflows, quality checks, and disagreement analysis are essential components of high-quality post-training datasets.
Quality Improves Training Efficiency
Better data can also improve how efficiently computational resources are used. Research published at EMNLP explored the concept of “effective training tokens,” linking data characteristics such as diversity and syntheticity with model performance.
More recent research has gone further by incorporating data quality directly into scaling-law frameworks, suggesting that model performance depends jointly on data volume and quality rather than volume alone.
The practical implication is straightforward: organizations should evaluate the learning value of their data rather than treating every token as equally valuable.
A well-curated dataset can help reduce wasted computation on irrelevant, duplicated, or low-value examples while concentrating training resources on information that contributes meaningful signals.
How Organizations Can Improve LLM Data Quality
A structured data-quality workflow can include:
Data sourcing: Select sources that align with the model's intended applications.
Cleaning: Remove corrupted, irrelevant, incomplete, or unsuitable examples.
Deduplication: Identify exact and near-duplicate content.
Filtering: Apply quality criteria to remove low-value or problematic examples.
Annotation: Add labels, preferences, classifications, or structured metadata where required.
Quality assurance: Use sampling, multi-stage review, adjudication, and consistency checks.
Dataset balancing: Monitor domain, language, intent, difficulty, and other relevant distributions.
Evaluation: Test whether improvements in data quality translate into measurable model improvements.
Importantly, quality should not be treated as a one-time cleanup step. Dataset composition should be continuously evaluated as new data is added and model requirements evolve.
Quality and Quantity Should Work Together
The debate between data quality and data volume should not be interpreted as meaning that dataset size is irrelevant. Large, diverse datasets remain valuable, particularly when additional data introduces new knowledge or coverage.
The more useful approach is to treat quality and quantity as complementary variables. Research on data curation shows that aggressive filtering can sometimes become counterproductive when a model repeatedly sees a small pool of high-quality examples, demonstrating that the optimal balance depends on training conditions and compute.
Therefore, the objective should not simply be to create the smallest possible dataset. It should be to build a dataset containing the highest-value information at the scale required by the model.
Build Better LLMs With Better Data
LLM development is moving beyond the simple assumption that bigger datasets automatically produce better models. As training pipelines become more sophisticated, data curation, annotation, validation, deduplication, and quality assurance are becoming strategic parts of model development.
For organizations building reliable generative AI systems, investing in high-quality training data can help create more useful and consistent learning signals while making better use of expensive computational resources.
At Annotera, LLM & GenAI annotation services can support the development of structured datasets for modern AI workflows, including instruction tuning, preference annotation, evaluation, and RLHF & fine-tuning data. By combining clear annotation guidelines with systematic quality assurance, organizations can transform large volumes of raw information into training data designed around measurable AI objectives.

Comments
Login to Comment