How to Annotate Overlapping Objects and Complex Visual Scenes
23 Oct, 2026
10 Views 0 Like(s)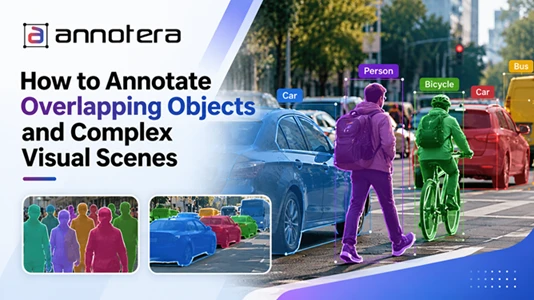
Learn how to annotate overlapping objects using segmentation, occlusion rules, and quality checks to build accurate computer vision datasets.
Computer vision models must interpret real-world environments filled with overlapping objects, partially hidden elements, complex backgrounds, and inconsistent lighting. From crowded retail shelves to busy roads and industrial environments, these visual challenges make accurate image annotation essential for developing reliable AI systems.
Annotating such scenes requires more than identifying objects. Annotation teams must distinguish individual instances, determine object boundaries, resolve occlusions, and maintain consistent labels across diverse visual conditions. Even small annotation errors can affect model performance, particularly when AI systems depend on precise object localization and scene understanding.
For businesses developing computer vision applications, understanding how to annotate overlapping objects and complex visual scenes is critical to building high-quality training datasets. With structured workflows and expert annotation support, organizations can improve dataset reliability and prepare their models for real-world complexity.
Why Are Overlapping Objects Difficult to Annotate?
Overlapping objects create ambiguity because multiple elements may occupy the same region of an image. An object positioned behind another may be only partially visible, making it difficult to determine its complete shape or boundaries.
For example, autonomous driving datasets frequently contain pedestrians partially hidden behind vehicles, cyclists moving through traffic, and road signs obscured by trees. Similarly, retail images may show products stacked closely together, while warehouse environments contain overlapping packages, machinery, and moving equipment.
These situations introduce several annotation challenges:
-
Partial visibility: Annotators must identify objects even when only a small portion is visible.
-
Ambiguous boundaries: Similar colors, textures, or shapes can make object separation difficult.
-
Dense object arrangements: Closely positioned objects may appear to form a single visual element.
-
Background interference: Shadows, reflections, and clutter can complicate object identification.
-
Inconsistent visibility: Changes in camera angle, lighting, and perspective can affect annotation decisions.
Addressing these challenges requires clear annotation guidelines, appropriate labeling techniques, and systematic quality assurance.
1. Choose the Right Annotation Technique
The first step in annotating complex visual scenes is selecting a method that matches the intended computer vision application.
Different annotation techniques provide different levels of detail and are suitable for specific training objectives.
Bounding box annotation identifies objects using rectangular boundaries. It is useful for object detection tasks involving vehicles, people, products, and equipment. However, bounding boxes may include surrounding objects or background regions when objects overlap.
Polygon annotation follows the visible contours of an object, providing more precise boundaries than rectangular boxes. It works well when objects have irregular shapes or appear close together.
Semantic segmentation assigns a class label to each pixel in an image. It helps AI models distinguish regions such as roads, buildings, vegetation, and pedestrians. However, because it labels pixels by category rather than individual object identity, separate instances of the same class may receive the same label.
Instance segmentation identifies individual object instances at the pixel level. It is particularly useful when multiple objects of the same category overlap, such as several people in a crowd or individual products on a shelf.
The appropriate technique depends on the model's requirements, dataset complexity, and desired annotation precision. Selecting the right method helps reduce ambiguity and improves the usefulness of the resulting dataset.
2. Establish Clear Rules for Occlusion Handling
Occlusion occurs when one object partially or completely blocks another object from view. Annotation teams need consistent rules for deciding how to label visible and hidden portions.
A practical approach is to annotate the visible region of an object when the task requires visible boundaries. Annotators should avoid inventing hidden contours unless the project specifically requires amodal annotation, which represents an object's estimated complete shape even when portions are obscured.
For example, if a pedestrian is partially hidden behind a parked car, the annotation should capture the visible portion according to the project's labeling rules. The hidden portion should not automatically be treated as visible or precisely known.
Projects should also define minimum visibility thresholds, truncation rules, and criteria for including heavily occluded objects. When an object cannot be identified confidently, annotators should follow an established uncertainty or escalation procedure.
These guidelines improve consistency and prevent different annotators from interpreting similar scenes differently.
3. Separate Objects with Similar Shapes and Appearance
Complex scenes often contain objects with similar colors, textures, and dimensions. Products on retail shelves, vehicles in traffic, and components on manufacturing lines can be particularly difficult to distinguish.
To address this issue, annotation teams should use contextual information alongside visual characteristics. Object position, surrounding elements, shape, and scene structure can help determine whether adjacent regions represent separate objects.
For instance, two similar packages placed side by side should be labeled as separate instances when the annotation task requires individual product identification. Annotators should examine visible edges, corners, shadows, and texture changes to identify the most defensible separation between them.
High-resolution images and zoom-enabled annotation tools can further improve boundary inspection. However, teams should avoid relying on contextual assumptions when the image does not provide sufficient evidence.
Consistent object separation is especially important for instance segmentation and applications that require accurate object counting or localization.
4. Use Consistent Class Definitions and Labeling Guidelines
Even technically skilled annotators can produce inconsistent datasets when class definitions are unclear. Complex visual scenes amplify this problem because object boundaries and identities may be difficult to interpret.
A comprehensive annotation guideline should define:
-
The visual characteristics associated with each class.
-
Rules for separating adjacent or overlapping objects.
-
Procedures for handling partial visibility and occlusion.
-
Instructions for labeling reflections, shadows, and transparent objects.
-
Minimum visibility requirements and exclusion criteria.
-
Examples of correct annotations and common mistakes.
Teams should maintain a shared reference library containing representative difficult cases. These examples help annotators resolve recurring ambiguities and support consistent decisions across large datasets.
Regular calibration sessions can also improve agreement between annotators, particularly when projects involve thousands of images or multiple annotation teams.
5. Apply Quality Assurance to Difficult Visual Cases
Quality assurance is essential when annotating overlapping objects because small boundary errors can propagate into model training.
A structured review process should prioritize images with dense object arrangements, low visibility, irregular shapes, and ambiguous class boundaries.
First, automated validation can identify missing labels, invalid class assignments, inconsistent annotation formats, and incomplete polygons or masks. Next, human reviewers should examine challenging images to verify object separation, boundary accuracy, and compliance with project guidelines.
Disagreements between annotators can be resolved through adjudication, where an experienced reviewer determines the appropriate label based on established rules.
Teams should also track recurring errors, such as merged instances, inaccurate contours, and missed partially visible objects. Analyzing these patterns helps identify training gaps and improve annotation instructions.
Quality metrics should reflect the project requirements. Depending on the task, teams may evaluate inter-annotator agreement, boundary accuracy, instance separation, and class-level consistency.
6. Use the Right Tools and Scalable Workflows
Annotation platforms can improve productivity by providing zoom controls, polygon editing, mask refinement, class selection, and collaborative review features. Some tools also support model-assisted pre-annotations that human annotators can correct.
These capabilities can reduce repetitive work, but automated predictions should not be accepted without validation. Models may merge adjacent objects, miss partially hidden elements, or generate inaccurate boundaries in crowded scenes.
A human-in-the-loop workflow combines automation with expert review. Straightforward images can move through the process quickly, while difficult cases receive additional attention.
For organizations managing large datasets, image annotation outsourcing services can provide access to trained annotation teams, standardized workflows, and scalable quality assurance processes. Working with an experienced image annotation company can also help businesses establish project-specific guidelines and maintain consistent labeling standards across complex datasets.
The most effective workflow balances annotation speed with accuracy rather than optimizing productivity at the expense of dataset quality.
How Annotera Supports Complex Image Annotation
Annotera helps businesses prepare high-quality visual datasets for computer vision applications through structured annotation workflows and quality-focused processes. From object detection and polygon labeling to semantic segmentation and instance-level labeling, annotation requirements can be aligned with the intended AI use case.
By establishing clear guidelines, reviewing difficult visual cases, and applying systematic quality checks, annotation teams can address overlapping objects and ambiguous boundaries more consistently.
Whether datasets involve retail products, road users, industrial equipment, or crowded environments, the objective is to create reliable training data that reflects the complexity of real-world scenes.
Conclusion
Annotating overlapping objects and complex visual scenes requires a combination of suitable labeling techniques, clear occlusion rules, consistent class definitions, and rigorous quality assurance. Bounding boxes, polygons, semantic segmentation, and instance segmentation each serve different purposes, making technique selection an important part of dataset planning.
Organizations should also invest in annotator training, difficult-case reviews, and scalable quality control to minimize labeling inconsistencies.
With the right processes and expert support, businesses can build more dependable computer vision datasets and improve the foundation on which their AI models learn to interpret complex environments. High-quality annotation is not simply a data preparation task; it is a critical investment in reliable AI performance.
Comments
Login to Comment