Redirect Chains vs. Redirect Loops: How to Diagnose URL Routing Problems
09 Oct, 2026
15 Views 0 Like(s)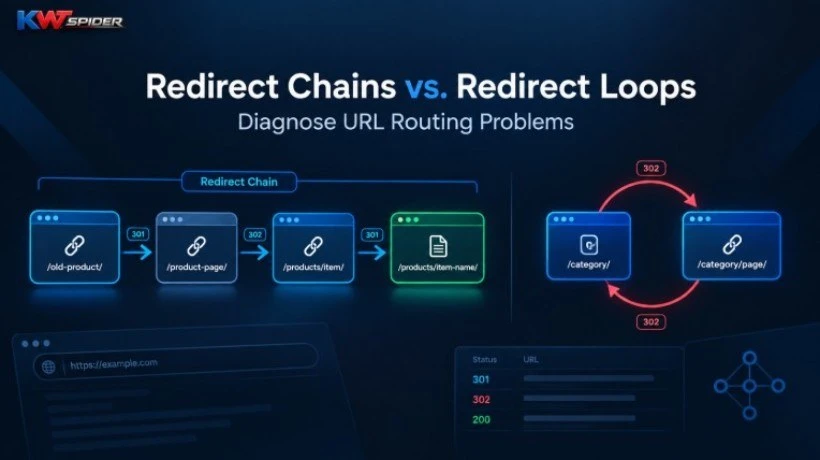
Learn the difference between redirect chains and redirect loops, discover their common causes, and explore how website crawling, HTTP status codes, and redirect path analysis help identify and resolve URL routing problems.
Redirection is an ordinary part of maintaining a website. They help preserve access to pages when URLs change, content moves, or outdated addresses want to point to something else. When configured effectively, manual redirects direct visitors and search engine crawlers to the ideal destination when navigation is impeded.
Problems can arise when several redirects are joined in succession or URLs again send requests to each other. These conditions create redirection chains and redirection loops. Although each involves URL routing, they behave differently and require separate methods for diagnosis.
Understanding these difficulties makes it easier to maintain a reliable website structure, protect current search visibility and guard against unnecessary crawl difficulties.
What Is a Redirect Chain?
A redirect chain occurs when one URL redirects to another, which then redirects a third one before reaching the final destination. Instead of taking site visitors to the supposed page without delay, the server makes them skip through more than one step.
For example, keep in mind a website that changes several instances of its URL structure:
* /old-product/ redirects to /product-page/
* /product-page/ redirects to /products/item/
* /products/item/ redirects to /products/item-name/
* /product-page/ redirects to /products/item/
* /products/item/ redirects to /products/item-name/
A traveler has to go through 3 redirects, curious for authentic deals before reaching the final web page.
This system is largely developed gradually. A previous migration can also trigger a redirect, a later redesign can also add another, and a subsequent move to HTTPS or new regulations can create yet another step.
The individual redirects might work correctly, but the entire route is unnecessarily complicated.
Why Redirect Chains Cause Problems
Long redirection sequences can increase web page load times because the technique requires additional requests to be made before the browser displays the vacation location. The actual delay depends on network conditions, server response times, and the number of redirects involved.
Search engines may also spend more time crawling URLs that pass through multiple redirects before reaching the final page. While search engines can observe redirects, useless steps complicate technical maintenance and can affect how efficiently important locations are found.
Another difficulty is hyperlink control. Internal hyperlinks pointing to previous URLs send traffic to crawlers in the same order. This creates avoidable work when the internet site is already aware of the best resting place.
Redirect chains can also make debugging more difficult. If an intermediate URL develops errors, numerous older addresses could be additionally affected even if their authentic redirect guidelines have not been changed.
What Is a Redirect Loop?
A redirect loop occurs when redundant URLs repeatedly redirect to each other without reaching the final web page.
For example:
* /category/ redirects to /category/page/
* /category/page/ redirects back to /category/
* /category/page/ redirects back to /category/
Neither address can make the last holiday location work because each request sends the browser back to the previous URL.
A redirect loop can also occur when a URL redirects back to itself. In either case, the browser eventually stops following redirects and displays an error message.
Unlike a chain, which eventually reaches a running stop, the loop has no successful endpoint.
Common Causes of Redirect Loops
Several configuration problems can produce this behavior:
- Conflicting redirect rules: Two rules send the same URLs toward each other.
- HTTP and HTTPS conflicts: One rule forces HTTPS while another sends requests back to HTTP.
- Trailing slash inconsistencies: Rules disagree about whether URLs should end with a slash.
- CMS or plugin settings: Application-level redirects conflict with server configuration.
- Incorrect redirect logic: Rules based on URL patterns may conflict with each other, causing URLs to redirect repeatedly.
- Reverse proxy configuration: The application and proxy disagree about the original request protocol or host.
These problems are not consistently obvious from the visual pages of the website. Even when server rules or plugins redirect URLs correctly, conflicting settings can still cause unexpected redirects.
Redirect Chains vs. Redirect Loops: Key Differences
There are a couple of URL responses to both issues, but they range in conduct and corrective needs.
A redirect chain occurs when a URL passes through multiple redirects before reaching its final destination. After that, the page loads but additional steps can increase the loading time and further complicate site maintenance. The best solution is to simplify the redirect path so that old URLs point directly to the intended destination.
A redirection loop occurs when URLs repeatedly send requests to each other without loading a running web page. Visitors also suffer from browser errors while crawlers cannot complete the affected path. Solving this difficulty requires thinking about and getting rid of the conflicting or circular redirection rule.
Understanding these variations makes interpreting the results of driving slowly less complex than choosing the right corrective pace. Chains generally need to be shortened while ropes require the underlying path fight to be constant.
How to Diagnose Redirect Chains and Loops
1. Start With a Website Crawl
A website crawl provides a clear overview of URL responses and redirect behavior across the site. Instead of checking URLs individually, a crawler identifies affected pages and shows how they connect to their final destinations.
Start with a Spider Crawl following internal links from the initial URL. Review the code with assigned redirect responses, vacation URLs, and ordinary routing styles.
List Crawl is useful when you want to see a particular series of URLs. For example, a migration spreadsheet, a list of website online traveler touch-pages, or a modern redirect map can be tested out relying entirely on internal links.
This distinction is difficult because some old URLs may not even be associated with a modern-day website but may still reach external site visitors or appear in historical search results.
2. Inspect the HTTP Status Codes
Redirects typically use HTTP status codes including 301 and 302. 301 indicates a permanent redirect while 302 typically indicates a temporary redirect.
During the audit, check which URLs return redirect responses and whether they lead to the expected destinations. Redirects can lead to the intended website rather than every other unnecessary step or unrelated vacation spot.
Also evaluate the final response. A route that ends with a 404 error, server error or other redirect deserves closer monitoring.
On my own, status codes don’t display a whole lot of trouble; They should be considered alongside URL sequence and closing availability location.
3. Trace the Complete Redirect Path
For each suspect URL, follow a series of redirects until it reaches a final response or repeats the previous deal.
As with each hop, still discover whether intermediate steps serve useful inspiration. If later unmarried has a state-of-the-art web page, the routing guidelines can be simplified so those older addresses now factor into the destination.
For a redirect loop, identify the exact point where the URL redirects back to a previously visited address. Compare the rules affecting each deal and decide which clashes with the stated URL structure.
Browser developer tools, command-line HTTP requests or a utility trying to redirect can help confirm a site crawl out-of-order.
4. Check Internal Links and Redirect Rules
Identify the affected URLs and see who they are originating from. Internal navigation, content links, breadcrumbs, XML sitemaps and server-level rules can all contribute to routing issues.
Update internal links so that they show preferred holiday destinations all at once rather than counting previous deals for redirecting traffic.
Next, evaluate the server configuration, CMS settings, plugins, and any proxy rules that affect URL behavior. Without knowledge, changing one rule to a higher quality can trigger another conflict.
The objective is to maintain constant route coverage of preferred protocols, hostnames and URL assignments and to comply with the Internet site-up cutdown configuration.
5. Retest After Making Changes
Once the rules are corrected, slowly navigate the affected URLs again. Confirm that chains have been shortened, loops have disappeared and important pages are returning to the predicted reputation codes.
Check the last positions of specific URLs. This makes it easy to verify that legacy addresses have been successfully redirected even if modern-day pages are still accessible.
For large websites, document the unique URL, expected vacation location, feedback received and corrective actions. This creates a beneficial context for future migration and stops returning omissions of previously resolved issues.
How KWT Spider Helps Identify Routing Problems
KWT Spider URL helps with technical SEO audits by collecting response data and organizing it to slowly drive conclusions into diagnostic approaches. Its redirect assessment can also help check for routing issues with chains, assessment destination relationships, damaged links, popularity codes and other crawl difficulties.
Spider Crawl is acceptable for discovering redirection behavior on internally linked pages while List Crawl evaluates the fixedness of default URLs. These options are beneficial when searching for a current site or validating redirects after a migration.
Reviewing redirect behavior with internal linking and page identification statistics additionally simplifies distinguishing remote formatting errors from problems affecting the entire URL sample.
Conclusion
Redirect chains and redirect loops look similar at some stage in technical SEO audits; However, they pose top-notch road hazards. Chains create useless steps before the destination is loaded while loops keep your requests from reaching the target endpoint.
A reliable forecast starts with slow-loading pages, which is observed using superstar signal evaluation, evaluating the entire redirect path and evaluating chargeable suggestions for each direction. After correction, every other crawl confirms whether the intended behavior is restored.
Regular redirect checks are especially valuable after site migrations, rebuilds, URL reorganizations and server configuration changes. Keeping routes direct and constant makes website navigation more reliable and reduces avoidable SEO difficulties.
Comments
Login to Comment